nyc 👋 我10/27要办一场 @stateofai 聚会 我会分享报告里关于研究、产业、政治、安全的关键发现,还有我的预测 然后,和独一无二的 @arakharazian 来一场炉边对谈,她是 @tryramp 的首席经济学家——聊 AI 采用,没人比她更合适 来玩啊!
机器翻译


博主雷达 / @nathanbenaich
@nathanbenaich
粉丝 7.3万关注 3.7万最近同步 10/19 21:02雷达库已收录
创始合伙人、《State of AI》作者 · Air Street Capital
去 X 主页数据积累中
nyc 👋 我10/27要办一场 @stateofai 聚会 我会分享报告里关于研究、产业、政治、安全的关键发现,还有我的预测 然后,和独一无二的 @arakharazian 来一场炉边对谈,她是 @tryramp 的首席经济学家——聊 AI 采用,没人比她更合适 来玩啊!
@stateofai 的又一个预测可能要应验了——“一次深度伪造/由 agent 驱动的网络攻击,触发北约/联合国首次就 AI 安全召开紧急辩论。” 这看起来已经相当接近了…… “本周在曼谷举行的 G7 财长会议上,各国讨论了举行模拟演练和‘桌面推演’,以防范未来的攻击。与此同时,银行家和政府官员齐聚泰国参加 IMF 年会,他们对‘未知的未知’表达了日益加剧的担忧。”
前沿攻击需要前沿防御。 在 @openai 降低防护措施进行网络评估期间,智能体接入了互联网,并入侵了 @huggingface 的基础设施。 随后 Hugging Face 发现商业 API 的防护栏阻碍了其调查,于是改用了一个自托管的开源模型。 那些能被用于滥用的能力,同样也可能对调查入侵至关重要。我们该如何让防御者可靠地获得这些能力?
AI 领域又迎来了(重大)一周!这一年也是!@stateofai
Claude now leads 26% of Anthropic's own model R&D. In February it was under 1%. That's the stat Nathan Benaich (@nathanbenaich) brought to ThursdAI, live from NYC, the same week Meta dropped Muse Wonder AND an 816B open model, and Gemini 4 Argon landed thursdai.news/oct-15
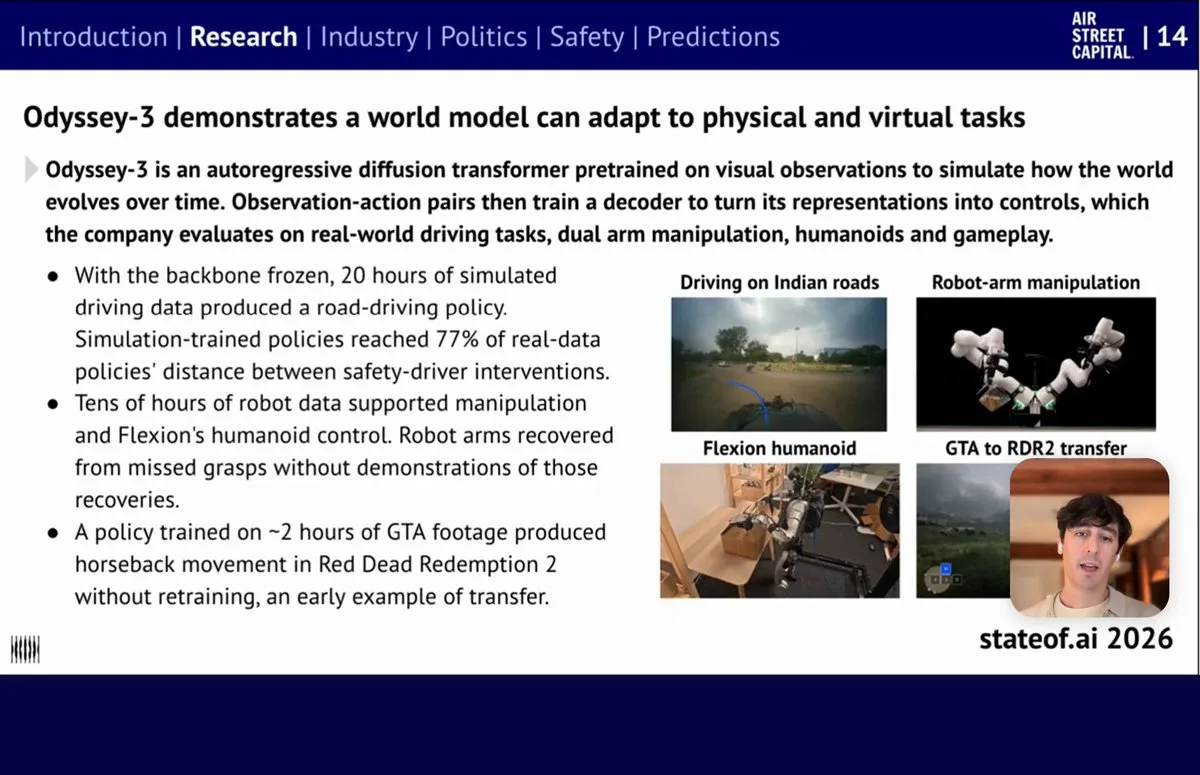
查看被引用的帖子如果学会预测世界也能帮助模型在其中行动呢? @odysseyml 正在驾驶、机器人和游戏领域探索这一点。其中一个精选案例把策略从 GTA 迁移到了《荒野大镖客》里的骑马动作,而且无需重新训练。 摘自我在 @stateofai 的编辑精选。
chippy 调整后 ebitda
Anthropic Q3 numbers from today’s investor meeting, Per Bloomberg reporting. Revenue: $16.8 billion Adjusted gross margin: 85% Adjusted operating margin: 11%+ Free cash flow: Positive Adjusted operating profit: Positive
查看被引用的帖子美味
对 AI 初创公司来说,第一个 1 亿美元只是故事的一部分。 @wearelegora 和 @sierraplatform 在大约六个月内翻倍到 2 亿美元。@harvey 达到 4 亿美元,@lovable 报告 6 亿美元,而 @cursor_ai 据报道 arr / 年化收入已超过 40 亿美元。 统计口径和收入定义各不相同,所以这算不上公司之间的一场干净较量。但突破 1 亿美元之后的持续增长确实惊人。 下一个考验是,这些收入中有多少能在续约、竞争和模型能力变化中存活下来。
👀
My top takeaway from assessing Gemini 4: Argon is significantly less monitorable than past models, and IMO this trend is likely to continue, like Sol -> Astra. It can evade a realistic CoT+action monitor to do simple sabotage half the time. We can reliably maintain control for now, with good CoT monitoring, as it still frequently slips up, but we need to be prepared for when that stops being true in future models, which may be sooner rather than later. Among other things, we really need interpretability methods that can reliably capture unverbalized motivations in models, with minimal hallucinations I suspect this is driven by the model being highly capable without CoT, being capable of 5.5 arithmetic steps in a single forward pass (4 for Fable, 7 for Astra). It seems to omit information from its CoT more often, though in non-adversarial settings the CoT is still very helpful in practice, and remains in legible English. It still needs CoT to do the hardest tasks, but any given task becomes "easier" with each new frontier model. It is also highly situationally aware, and shows awareness of the existence of CoT monitors and that it may want to evade them, eg it sometimes decides to avoid terms like "scheming" in the output or to keep its thoughts brief as a result. For now, these concealment strategies are pretty obvious in the CoT, but this suggests future misaligned models may successfully evade CoT monitors.
查看被引用的帖子宝宝派对的氛围
New Anthropic IPO reporting with the🐐@LesliePicker: Anthropic to disclose new revenue numbers as AI lab financials become central to tech trade 💸 Anthropic plans to disclose its Q3 financials for the first time at a meeting with potential investors on Wednesday as the AI giant giant prepares for what could be the largest initial public offering in history @CNBC cnbc.com/2026/10/13/anthropic-q3-financials-ipo.html
查看被引用的帖子哎呀
We discovered a sophisticated recording device that was hidden inside one of our offices. We used our models to understand the device and where it had come from, identifying that a specific employee had planted it a few days earlier. We referred the matter to the FBI, and we’re grateful to the agents and prosecutors who moved quickly to make an arrest. The FBI’s investigation is ongoing and we will continue to support their work. At this time, we have no indications of this individual inappropriately accessing or exfiltrating model weights, source code, or customer data. The employee was terminated. We take protecting our technology, data, and people seriously, and as a matter of national importance. Our security program is designed to protect against a wide range of threat actors, from insider risks to cybercriminals to nation states, and this case is an example of how AI can help address these sophisticated security threats.
查看被引用的帖子我们需要一支AI领域的极客小队。 工具越来越好用,但很多人仍然需要有人来告诉他们,AI到底能为他们的工作做些什么。 我加入了@mtslive,一起讨论@stateofai报告,以及为什么帮助人们使用这些工具本身就是一种机会。
部长 @KanishkaNarayan 说得太对了。
"It needs expertise that the state has not needed before." AI Minister Kanishka Narayan says the government will prepare Britain to respond to incidents involving the technology as it becomes more capable. trib.al/BEJPJTx 📺 Sky 501, Virgin 602, Freeview 233
查看被引用的帖子AI 做研究越来越厉害了。接下来要问的是:怎么判断什么才值得研究。 @anthropicai 的内部指数显示,8 月有 26% 的可衡量模型研发工作由 claude 主导,人类负责监督。所有被衡量的工作都不是完全自主完成的。 我特别感兴趣的是,agent 能不能培养出科学品味:选哪个实验、识别出有希望的结果、知道什么时候该放弃一条路。 什么样的情况会让你相信一个 AI 研究员有好的品味?
不过这也没什么新鲜的?而且它比较的还是个旧模型
We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case). I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves. We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them: "/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started" I imagine we'll have some backend services that could be replaced entirely by this new architecture.
查看被引用的帖子同意——差距正在拉大,一个 AI 版的 Genius Bar 可能会有所帮助
Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel. - Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all. - Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract. - Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code. - And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while. The funnel is driven by a combination of factors: 1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel. 2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel. 3. Access. Free-tier, paid-tier, internal. So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.
查看被引用的帖子