

博主雷达 / @mervenoyann
merve
AI开发者与产品@mervenoyann
粉丝 9.3万关注 5,496最近同步 10/19 20:41雷达库已收录
开源负责人(视觉/多模态) · Hugging Face
去 X 主页粉丝趋势近 30 天
近 7 天
数据积累中
情报贡献参与 1 条已上架情报 · 首发 1 条
- 新产品Hugging Face Hub 上线 RL 环境数据集专区10/17 21:20
最近帖子最多 20 条
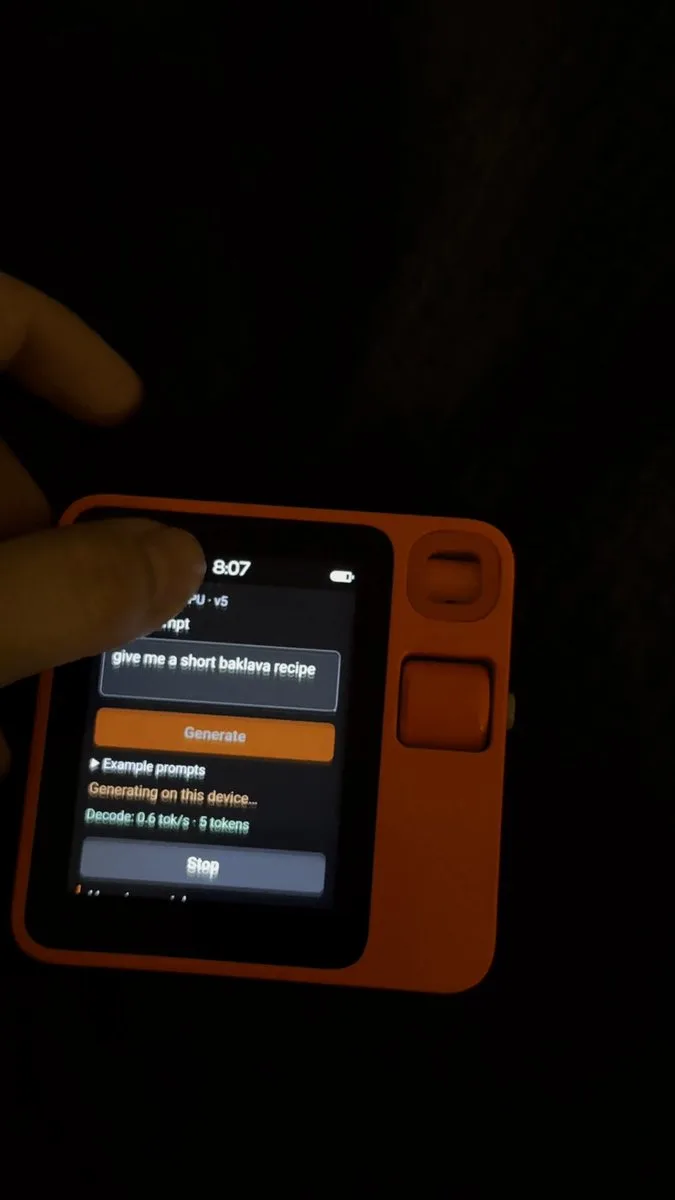
更新:我没法直接下载 llama.cpp,所以用 @ngxson 的 wllama 做了个东西,在 Rabbit R1 上跑 Qwen3.5-0.8B 的 4-bit 量化版
机器翻译
merve@mervenoyann
I was thinking of buying a teenage engineering sampler as I love their stuff then I remembered I have a rabbit r1 I'm thinking of installing llama.cpp on it but also doing s2s apps tbf initially I wasn't as interested but now they offer you to vibe code apps, use community creations on device or jailbreak which to me is very cool probably need to upgrade the os first disclaimer: this was sent to me for free but it's not a paid ad or whatever, I do not do paid ads and never did
查看被引用的帖子开源 AI 创造的经济价值无可匹敌
机器翻译
Thomas Wolf@thom_wolf
Fun and crazy napkin math: Meta, NVIDIA, Alibaba, DeepSeek, Moonshot, Mistral and ~30 other labs have shared close to $1B worth of training compute on the Hugging Face Hub Free to download End of 2023 it was under $40M Wikipedia was written in volunteer hours. This AI age commons is written in GPU-hours and data (it's a floor btw: about half comes from official compute numbers rest is educated guess and it still miss the ~900k community fine-tunes) Space with data to explore: thomwolf-hub-dollars.static.hf.space
查看被引用的帖子
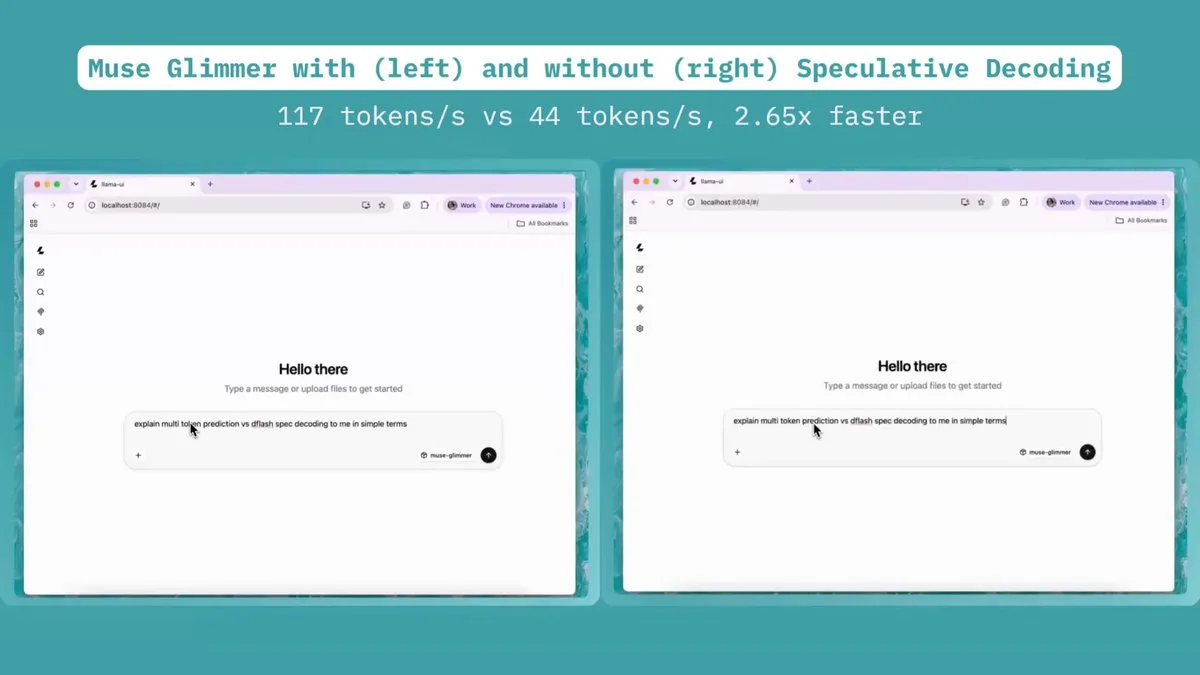
友情提醒:这是周一的事 🤝 → 了解投机解码(speculative decoding),用来加速推理 → 如果你是新手而且不感兴趣,直接用 llama.app 就行,它会自动帮你搞定这些 🦙
机器翻译
Hugging Face@huggingface
Learn about how to get multipliers in local LLM speed-ups using speculative decoding in this livestream with @mervenoyann, @MaartenGr and @_EldarKurtic youtube.com/watch?v=H4azmWcqO5g
查看被引用的帖子顺便说一下,Hugging Face Hub 现在成了 RL 环境的一站式商店 huggingface.co/datasets?other=rl-environment&sort=trending
机器翻译
Beam 是一个面向编程智能体的前沿规模模型,token 效率很高,还自带配套 harness 🔥 A23B/501B 模型,同时提供 NVFP4 和 FP8 版本,并且 day-0 支持 transformers 🤗 来看看我们的博客 ⤵️
机器翻译
Reflection@reflection_ai
Beam is now available across platforms, with open weights under the Apache 2.0 license - in collaboration with an ecosystem of 40+ partners. We're releasing: - Weights, tokenizer, and reference implementation - BF16, FP8 and NVFP4 weights and a DFlash2 drafter - The open source harness we built and trained Beam on: Mirror CLI Weights and model card on Hugging Face: huggingface.co/reflection
查看被引用的帖子llama serve -hf ggml-org/Muse-Spark-Open-816B-A42B-GGUF:Q2_K 这个模型搭配 @pidotdev 的 agent 干活也超顺手!🤯
机器翻译
Pedro Cuenca@pcuenq
And of course Muse Spark Open works great with llama.cpp 🦙🔥 Behold this amazing demo courtesy of @mervenoyann, running on a Mac (M3 Ultra 512). This is a frontier model that runs on your (beefy) desktop. Local AI is only getting better 🚀
查看被引用的帖子Meta 发布 Muse Spark Open,成为美国最强的开放权重模型.. 🥁 而且它是一个专注于 agent 的 MoE,支持所有模态 🔥 欢迎这个模型加入 Hub,transformers 和 llama.cpp 首日即支持 🤗 huggingface.co/blog/meta-muse-spark-open
机器翻译
这太炸了
机器翻译
Arthur Zucker@art_zucker
Yesterday and today I worked on the new "decision" pipeline to support all `jev`-like models in `transformers`. This will bring good standards in the mayhem that the ecosystem is now 👀 Meaning support for all jev/clef/von/etc via the simple and efficient `transformers serve`
查看被引用的帖子下周来跟我们一起了解投机解码吧!
机器翻译
Hugging Face@huggingface
Learn about how to get multipliers in local LLM speed-ups using speculative decoding in this livestream with @mervenoyann, @MaartenGr and @_EldarKurtic youtube.com/watch?v=H4azmWcqO5g
查看被引用的帖子大家都在用 EmbeddingGemma 2 做出超酷的东西,我很开心嵌入模型终于得到了应有的关注
机器翻译
Shahir@tslshahir
I turned @googlegemma EmbeddingGemma 2, an embedding model, into a speech-to-text model, and it turned out to be one of the fastest STT models you can run on device. On a base M3 MacBook Air it transcribes an hour of audio in about 13 seconds: 288× real time. The idea came in March with Gemini Embedding 2. It puts text, images, audio and video into one shared space, so a spoken word lands right next to the written word. If that's true, you should be able to read a transcript straight out of the embedding model. I couldnt tried it then, but last week EmbeddingGemma 2 came out as an open model, so I tried it.
查看被引用的帖子