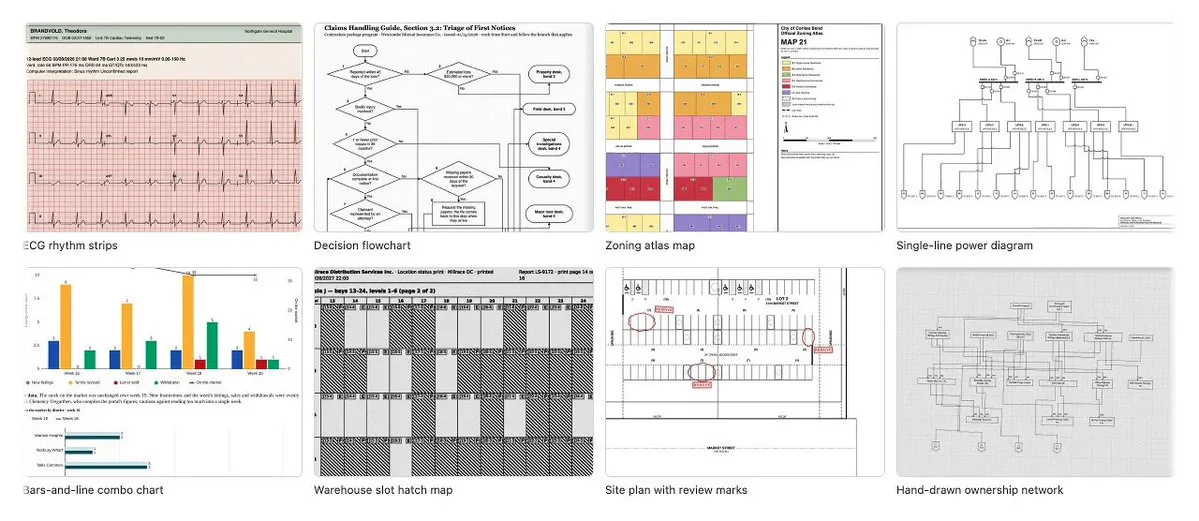
推进企业级 AI 最重要的挑战之一,是创建能反映企业真实数据和工作流的评估基准——同时又因为隐私/安全限制,不能使用它们实际的数据或工作流 我们看到客户上传了大量长尾的复杂文档用于抽取,这些文档连最复杂的前沿模型都能难倒。 为了创建一个能贴合这种复杂度的、有代表性的基准,我们投入了大量精力搭建了一条合成流水线,它可以挖掘真实的文档模板,同时又能灵活地变化数据,甚至模板和渲染方式。 来看看 ExtractBench Pro 吧!llamaindex.ai/blog/introducing-extractbench-pro 网站:extractbenchpro.ai
Introducing ExtractBenchPro: the most challenging benchmark for real-world document extraction. We see a massive long tail of document complexity in terms of use cases brought on from our customers, that are completely unsolved from a price-performance standpoint. These include trial balances, well logs, canvass binders, site plan reviews, duty reconciliations, loss runs, and more. Most existing extraction benchmarks are saturated by the frontier models (our cheapest modes now score 93%+ on ExtractBench). So there is enormous economic value in building a complex extraction benchmark that reflects this long-tail of knowledge work. We spent a long time curating the most complex elements that we saw from real world extraction use cases: ✅ Document conventions: containing legends or rules where the rest of the document should be interpreted ✅ Density of internal jargon: specific definitions that must be cross-referenced within a doc ✅ Aggregation and reasoning: beyond returning exact values on a page, infer values derived from aggregating multiple sources of information ✅ Drawn relations: complex diagrams like procedures and circuits ✅ Charts inside documents: read precise points within a chart ✅ Long chart sheets: some data series like well logs cram all this data into an extremely long page Within the industries where document extraction is relevant, even small mistakes can have enormous negative impacts. Therefore our headline evaluation metric is based on perfect documents: the proportion of docs with perfect (100%) value f1 score. (Besides this we also measure value f1 and grounded f1) It’s an extremely hard task for even the latest frontier models to solve, topping out at ~58% or so in Value F1 score for Codex with Astra - which is quite good but extremely expensive (almost $1 per page!) Our LlamaParse agentic/agentic plus modes are 20-40% and cover the left side of the Pareto frontier, at price ranges that are feasible for full production use. ExtractBenchPro is available today as a website/technical blog, and also on Github and HuggingFace. Check it out! Blog: llamaindex.ai/blog/introducing-extractbench-pro Website: extractbenchpro.ai/ Hugging Face: huggingface.co/datasets/llamaindex/ExtractBenchPro Github (is ExtractBench): github.com/run-llama/ExtractBench
查看被引用的帖子