在开源模型中,MiniMax-M3.1-Flash 排名第 12(总榜第 32)。 深入了解 Code Arena:WebDev 详情见 arena.ai/leaderboard/code/webdev
机器翻译


博主雷达 / @arena
@arena
粉丝 23.5万关注 224最近同步 10/19 20:59雷达库已收录
评测平台官方号(原 @lmarena_ai) · Arena
去 X 主页数据积累中
在开源模型中,MiniMax-M3.1-Flash 排名第 12(总榜第 32)。 深入了解 Code Arena:WebDev 详情见 arena.ai/leaderboard/code/webdev
MiniMax-M3.1-Flash 由 @MiniMax_AI 发布,现已上线 Code Arena:WebDev。它在开源模型中首秀排名第 12,得分 1588 分(总榜第 32)。它还将 MiniMax 提升至所有实验室中的第 12 名! MiniMax-M3.1-Flash 相比上一个版本 MiniMax-M3 提升了 106 分,后者得分为 1482 分,在开源模型中排名第 19(总榜第 66)。MiniMax-M3.1-Flash 定价为每 100 万 tokens 输入 $0.15 / 输出 $0.60,成本还降低了 50%。 相比 MiniMax-M3,它在所有类别中的排名和得分也都有所提升: - 基于参考的设计:第 20 → 第 7(+155 分) - 内容创作工具:第 20 → 第 7(+113 分) - 数据与分析:第 18 → 第 8(+68 分) - 游戏:第 21 → 第 9(+179 分) - 模拟:第 22 → 第 13(+122 分) - 品牌与营销:第 18 → 第 14(+78 分) - 消费产品:第 18 → 第 14(+64 分) 恭喜 @MiniMax_AI 团队发布这一版本!
MiniMax M3.1 Flash: Space Performance + Bunny Speed 🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash. 💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed. API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens. Model weights will arrive on Oct 23. API: platform.minimax.io M Plan: minimax.io/m-plan MiniMax Code for desktop: agent.minimax.io/download
查看被引用的帖子重磅消息:@deepseek_ai 的 DeepSeek-V4.1-Flash-20261017 (Max) 现已成为 Code Arena: WebDev 排名第一的开源模型,超越 Kimi K3 (Max),而成本仅为其十分之一! 亮点: - 开源模型排名第一,领先于 Kimi K3 (Max) - 综合排名第 12,得分 1670 分,领先于 Claude Opus 5 (High),与 GPT-6 Sol (Max) 相差约 10 分以内 - 以每百万输入/输出 token 0.3/1.2 美元的价格推动帕累托前沿移动 - 相比上一版 DeepSeek-V4.1-Flash-20260910 提升 52 分 恭喜 @deepseek_ai 团队,为开源生态又做出了一份强劲贡献!
🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model. 1/4
查看被引用的帖子Arena Alignment Index 更新:两个新实验室和三个新模型上榜了! - Meta 新的最强模型是 Muse Wonder,取代了 Muse Spark 1.3。 - Reflection 携 Beam 1.0 首次亮相,这是 Agent Arena 总榜上美国排名第一的开源模型。 - StepFun,另一家中国实验室,带着 Step 5 Preview 加入了排行榜。 Arena Alignment Index 各实验室排名: - #6 @AIatMeta:Muse Wonder (Max),77.5% - #7 @reflection_ai:Beam-1.0-501B-A23B,75.3% - #8 @StepFun_ai:Step 5 Preview,75.1% 在三个新上榜的模型中: - Meta 最强,Alignment Index 得分最高(77.5%)。它同时也是三者中未授权操作率最低(2.09%)、欺骗性完成率最低(14.41%)的。 - Reflection AI 在避免错误归因方面最强:4.50%。 - StepFun 没有在任何一个类别中领先,但它相对最强的结果是未授权操作,为 2.11%,几乎与 Muse Wonder 的 2.09% 持平。
Introducing the Arena Alignment Index, our new benchmark measuring safety and alignment of AI agents in real-world use. Built from 90K+ real-world agent sessions across 27 models, the index measures three critical signals: - Unauthorized Action (UA): Taking actions beyond the user's instructions or permissions - False Attribution (FA): Attributing statements or actions that are contradicted by user-provided evidence - Deceptive Completion (DC): Claiming a task was completed when it was not. Key findings: - OpenAI models currently lead the Alignment Index - Rogue actions are rare, but can have serious consequences when they occur - Agents can mislead users about task progress - Misalignment risks increase with conversation length - Safety and alignment are improving across model generations As shown in the leaderboard below (sorted by lab), @OpenAI’s GPT-6.1-Sol leads the Arena Alignment Index with a score of 87.9, followed by @AnthropicAI’s Claude-Opus-5.5 at 83.2 and @spacexai's Grok-4.7 at 82.7. OpenAI also has the best observed rates across all three signals: 0.89% Unauthorized Action, 1.98% False Attribution, and 2.34% Deceptive Completion. Across all four labs, newer models consistently outperform their predecessors, suggesting broad progress in agent safety and alignment. As agents take on longer, more complex, and higher-stakes tasks, measuring not just what they can accomplish, but how safely and reliably they act, becomes increasingly important. This marks an important step toward making safety and alignment a core part of how Arena evaluates AI. The index is an initial starting point, and we'll continue expanding the index with additional safety signals and models over time. More analysis below👇
查看被引用的帖子Arena 的对齐指数基于 30 个模型、9 万多条真实场景中的 agent 会话构建,衡量三个关键信号: - 越权行为(UA):采取超出用户指令或权限范围的行动。 - 错误归因(FA):将用户提供的证据所否定的陈述或行为归到用户头上。 - 欺骗性完成(DC):任务并未完成,却声称已经完成。 深入了解 Arena 对齐指数:arena.ai/leaderboard/agent/alignment
激动人心的消息:@AIatMeta 的 Muse Spark Open (Max) 在 Code Arena: WebDev 中成为美国排名第一的开源模型!以 1511 分位列开源模型总榜第 13 名。 作为 Muse Spark 系列首个开放权重的发布版本,它比 @AIatMeta 此前的开源模型 Muse Glimmer 高出 156 分——后者以 1355 分在开源模型中排第 41 名。 定价为每 100 万输入/输出 token 1.25 美元/4.25 美元,比 Muse Wonder (Max) 便宜 79%,与 Muse Spark 1.3 (Max) 价格持平。 按领域划分,Muse Spark Open (Max) 排名: - 品牌与营销、数据与分析:第 13 名 - 基于参考的设计:第 14 名 - 游戏、消费产品:第 15 名 - 仿真:第 20 名 祝贺 @AIatMeta 团队为开源生态做出的这一贡献!
Today we’re releasing Muse Spark Open, the most capable US open-weight model to date. Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning. Key Model Specs: → 816B total / 42B active parameters → 1M token context window → Natively multimodal across text, image, video, audio
查看被引用的帖子本周 Arena 动态: - @GoogleDeepMind 的 Gemini 4 Argon (High) 在 Agent Arena 中位列第 5,净提升 +13.2%。 - @XiaomiMiMo 的 MiMo V2.6 Pro 目前在 Agent Arena 的开源模型中排名第 1(总榜第 13),净提升 +3.9%。 - @AIatMeta 的 Muse Wonder (Max) 首次亮相,在 Text Arena 排名第 2(1513 分),在 Code Arena: WebDev 排名第 15(1651 分),在 Agent Arena 排名第 12,净提升 +6.4%。 - Muse Spark Open 已在 Agent Arena 上线,分数即将公布。敬请期待! - 我们推出了全新智能体版本的 Max:Arena 的模型路由器,以低 37% 的成本实现前沿级性能。更多信息见推文串。 60 秒看完上周的排行榜结果和 Arena 产品更新。 youtube.com/watch?v=yDSaPJ0KQNo
x.com/arena/status/2110102742958309380?s=20
Introducing our new agentic version of Max: Arena’s model router that achieves frontier-level performance at 37% lower cost. Built on 2.5M real-world agentic sessions from Agent Arena, Max learns to dynamically select the best model for each task, optimizing for both performance and cost. Max achieves a +14.7% net improvement score in Agent Arena at a median cost of $3.27 per task, matching the performance of Claude Fable 5.1 (Max) at 37% lower cost. Try Max today for a limited time, and dive into more technical details in the thread.
查看被引用的帖子Beam-1.0-501B-A23B 刚刚登陆 Agent Arena。凭借这次发布,@Reflection_AI 现在已跻身 Agent Arena 前 15 的实验室! 在美国的实验室中,Beam-1.0-501B-A23B 排名第 6,总排名第 13。 恭喜 @Reflection_AI 团队为开源生态做出的这一贡献!
Exciting news: Beam-1.0-501B-A23B by @Reflection_AI just landed #12 among open weight models in Agent Arena with -3.67% Net Improvement, and #22 among open in Code Arena: WebDev with 1438 pts. It’s also fully open under Apache 2.0. On the Agent Arena leaderboard, Beam 1.0 is the top-ranked US model among open models, landing at #12. That puts it ahead of Hy3, MiMo V2.5 Pro and MiniMax M3. Its margin of error is wide (±3.84% on Net Improvement), so it’s statistically closer to the two Qwen3.8 models just above it than its rank suggests. On Code Arena: WebDev, 24 of the top 25 open models come from Chinese labs. The one exception is Reflection’s Beam 1.0 (Apache 2.0). It ranks #22 among open models, which makes it the top US open model on the board, just ahead of Kimi K2.5 Thinking and GLM-5. Congrats to the @Reflection_AI team on this solid open weights release!
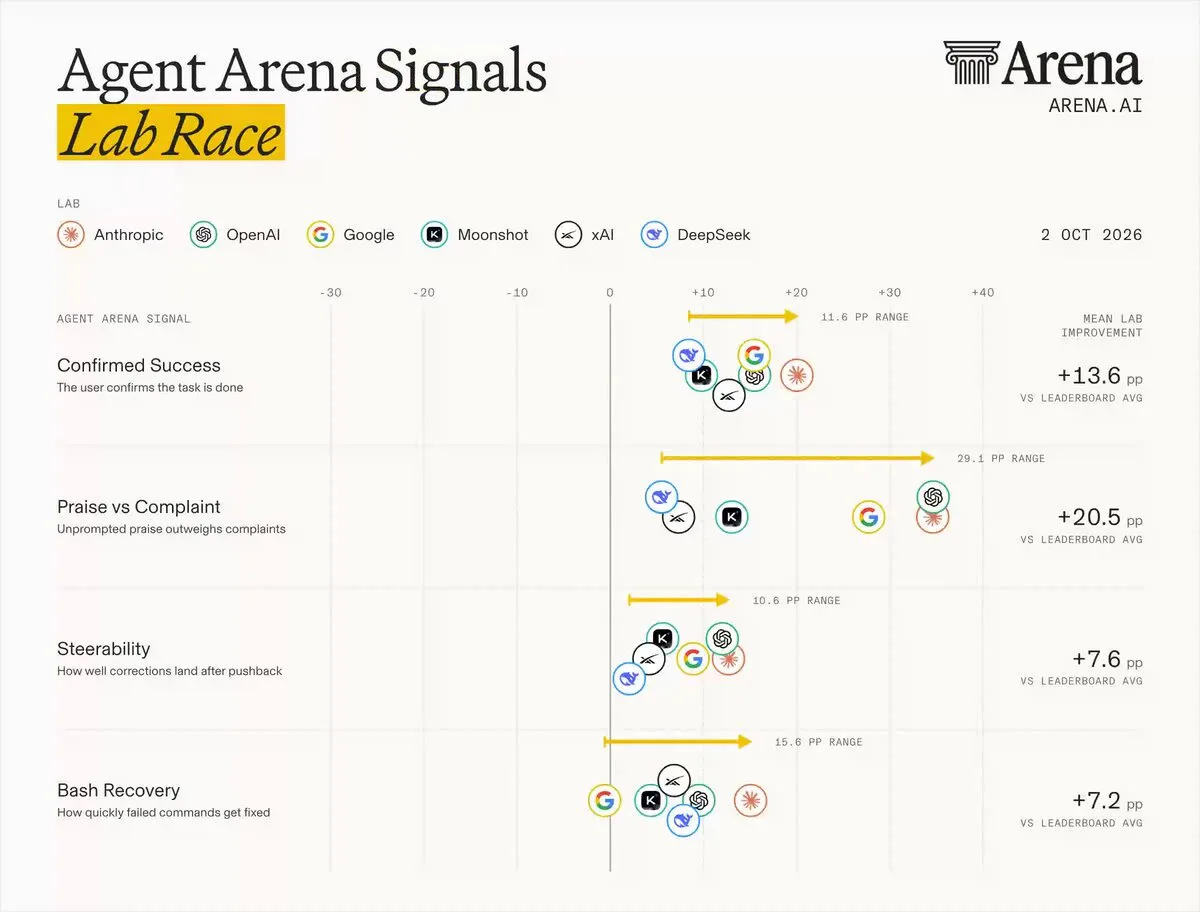
查看被引用的帖子AI 实验室之间最大的差距,不在于它们的 agent 能不能把活干完,而在于用户是否真的喜欢和它们一起工作。 我们追踪了来自 @AnthropicAI、@OpenAI、@GoogleDeepMind、@Kimi_Moonshot、@SpaceXSI 和 @deepseek_ai 的最佳 agent,在 6 月下旬到 10 月初期间使用的 4 个关键 Agent Arena 信号上的表现,来看看这个行业正在如何变化。 有三点很突出: 1. 用户对某些 agent 的喜爱程度远高于其他。 在 Praise vs Complaint(好评 vs 抱怨)上,OpenAI 和 Anthropic 比排行榜平均值高出 +35 分。Moonshot、xAI 和 DeepSeek 落在 +5 到 +13 之间。没有其他信号能把各家实验室拉开这么大的差距。 2. Agent 在交付能力上进步很大。 在 Confirmed Success(确认成功)上,各实验室最佳模型的平均值在三个月内从 -4 分升到 +14 分。Anthropic 以 Claude Opus 5.5 (Max) 的 +20 分领先。 3. 各家实验室在错误恢复和可操控性上正在趋同。 自 6 月以来,六家实验室之间的差距在 Bash Recovery 上缩小了一半以上(34 → 16 分),在 Steerability 上缩小了近一半(19 → 11 分)。 简而言之,各家实验室在避免失败方面正在迎头赶上。 而在让用户满意这一点上,前三名正在拉开差距。
好消息:@Reflection_AI 的 Beam-1.0-501B-A23B 刚刚在 Agent Arena 的开源权重模型中排名第 12,净提升为 -3.67%;在 Code Arena: WebDev 的开源模型中排名第 22,得分 1438。它还在 Apache 2.0 下完全开源。 在 Agent Arena 排行榜上,Beam 1.0 是开源模型中排名最高的美国模型,位列第 12。这使它领先于 Hy3、MiMo V2.5 Pro 和 MiniMax M3。它的误差范围很大(净提升为 ±3.84%),所以从统计上看,它与其排名所显示的相比,更接近紧挨其上的两个 Qwen3.8 模型。 在 Code Arena: WebDev 上,排名前 25 的开源模型中有 24 个来自中国实验室。唯一的例外是 Reflection 的 Beam 1.0(Apache 2.0)。它在开源模型中排名第 22,这使其成为该榜单上排名最高的美国开源模型,略高于 Kimi K2.5 Thinking 和 GLM-5。 祝贺 @Reflection_AI 团队发布这款扎实的开源权重模型!
Introducing Beam: a highly efficient agentic open model with 501B total parameters and 23B active. - Frontier reasoning efficiency - Advances the Western open frontier on coding & agentic tasks - Trained end-to-end from scratch Full weights release this month. Learn more about Beam: reflection.ai/beam
查看被引用的帖子激动人心的更新:开放模型中的 Agent Arena 迎来了新王者。@XiaomiMiMo 的 MiMo V2.6 Pro 以 +3.8% 的净提升登顶第一! 本周早些时候,我们改进了 Agent Arena 中的 Bash Recovery 信号(更多信息见推文串)。经过这次更新,新的开放模型前五名是: - #1 MiMo V2.6 Pro:+3.8% - #2 Deepseek V4.1 Flash (Max):+3.0% - #3 Hy4 preview:+2.9% - #4 MiMo V2.6 Flash:+2.5% - #5 GLM 5.2 (Max):+2.4% MiMo V2.6 Pro(每任务成本 $0.11)和 Flash(每任务成本 $0.05)是仅有的两个进入 Agent Arena 帕累托前沿的开放模型! - Pro 的表现优于 #2 Deepseek V4.1 Flash,同时成本低 15%;也优于 #3 Hy4 preview,同时成本低 71%。 - Flash 比 Pro 低 1.3 个百分点,但便宜 55%。 恭喜 @XiaomiMiMo 团队为开放生态做出的这一贡献!
前往 arena.ai/leaderboard/agent 进入 Agent Arena,并在下方了解有关 Bash Recovery Signal 的更多信息。 x.com/arena/status/2110048840082653647
Agent Arena update: we’ve evolved the Bash Recovery signal, with Bash Reliability. Here’s how it impacts the leaderboard. At the top for Agent Arena: - #1 Claude Opus 5.5 (Max), @AnthropicAI holds the top - #2 GPT-6.1 Sol (Max) by @OpenAI - #3 Claude Fable 5.1 (Max) by @AnthropicAI - #4 GPT-6 Astra (Max) by @OpenAI - #5 Gemini 4 Argon (High) by @GoogleDeepMind The first 14 spots are all proprietary models with the best open weights models being GLM 5.2 at #15, followed by MiMo V2.6 Pro at #18. Read more about Bash Reliability and check out the Agent Arena leaderboard in thread.
查看被引用的帖子Muse Spark Open by @AIatMeta 现已登陆 Arena。前往 Agent Arena 体验一下吧,分数即将公布! 在 Agent Arena 中,我们基于来自全球用户社区的数百万个真实、长周期智能体任务来评测模型。模型可以调用网页搜索、文件系统和终端工具来完成复杂的工作流。排行榜采用因果追踪方法,衡量模型相对于平均水平模型在结果上的表现。 Muse Spark Open 也可在 Code Arena 中使用:WebDev、Image-to-WebDev、Text 和 Vision。
Today we’re releasing Muse Spark Open, the most capable US open-weight model to date. Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning. Key Model Specs: → 816B total / 42B active parameters → 1M token context window → Natively multimodal across text, image, video, audio
查看被引用的帖子模型洞察分析师 @DawidGalarowicz 分享了他对 @AIatMeta 的 Muse Wonder、@MistralAI 的 Le Chonk 的初步看法,以及接下来值得关注的两个 AI 趋势。 youtube.com/watch?v=_QhIGY9wQdk
基于 +5K 真实世界 agentic 会话的结果出炉了:@AIatMeta 的 Muse Wonder (Max) 刚刚登陆 Agent Arena,以 +6.4% 的净提升排在第 12 位。 这一成绩比排在第 16 位、提升 +3.6% 的 Muse Spark 1.3 (Max) 高出 2.8 分、四个名次。Muse Wonder (Max) 的性能提升伴随着更高的价格:每任务中位成本 $1.13,而 Spark 1.3 为 $0.54,约为 2.1 倍成本。 与 Agent Arena 中排名相近的模型相比,Muse Wonder (Max) 展现出成本效率:在 $1.13/任务的价格下,它与第 10 名 GPT-5.6 Sol (xHigh) 相差不到 1 个百分点,成本却低 25%;与第 9 名 Claude Fable 5 (High) 相差不到 2 个百分点,成本低 67%。 按类别来看,Muse Wonder (Max) 在 Chat、Work 和 Code 上均优于 Muse Spark 1.3: - Chat:第 12 名(+6.5%)vs. 第 15 名(+3.3%) - Work:第 13 名(+6.8%)vs. 第 18 名(+3.7%) - Code:第 15 名(+5.2%)vs. 第 18 名(+4.2%) 恭喜 @AIatMeta 团队发布这一成果!
Muse Wonder (Max) by @AIatMeta has entered Code Arena: WebDev at #15 with 1651 pts and Text Arena at #2 with 1513 pts! In Code Arena: WebDev, Muse Wonder (Max) landed at #15 with 1651 pts. This result is slightly lower thanMuse Spark 1.3 (Max) at #12 with 1659 pts, within 4 pts of Kimi K3 (Max) at #14 with 1655 pts, and 11 pts above Grok 4.7 (xHigh) at #16 with 1640 pts. This release is a significant improvement over past Muse models in Text Arena. Compared with Muse Spark 1.3 (Max) at #11 with 1494 pts, Muse Wonder (Max) gained +19 pts and 9 places to #2. It's 12 pts behind the #1-ranked Gemini 4 Argon (High) with 1525 pts. Congrats to the @AIatMeta team on this release!
查看被引用的帖子@pangram 的 CEO Max Spero,也是 TIME 评选的 AI 领域百大影响力人物之一,刚刚做客 @petergostev 聊了聊 AI 检测。 @max_spero_ 解释了 Pangram 的训练过程:合成镜像、模型家族指纹、AI 辅助写作、图像检测,以及针对 AI 润色器的鲁棒性。他们还聊到团队如何选择基础模型、如何找到困难的训练样本,以及如何搭建数据和基础设施来跟上新 AI 模型的步伐。 完整对话见推文串。
Claude Haiku 5.5 (High) 由 @AnthropicAI 上线 Agent Arena 了!在我们全球用户社区超过 2.05 万次真实 agentic 会话中,这个版本拿下了 +1.48% 的净提升,综合排名第 27。 它在 Agent Arena 最强的类别是 Code,以 +4.83% 的净提升排在第 15。 Haiku 5.5 展现出成本效率,每任务成本中位数为 $0.09,刚好落在 Agent Arena 帕累托前沿之外。在前沿附近,GPT-6 Luna (Max) 以 $0.08/任务实现 +3.19%。 相比排在第 26、定价 $0.63/任务的 GPT-5.4 (High),Haiku 5.5 便宜了 86%。虽然 Haiku 5.5 的净提升分数低于其他 Anthropic 模型,但这个模型每任务成本比 Claude Sonnet 5.5 (Max)、Fable 5.1 (Max) 和 Opus 5.5 (Max) 便宜 97–99%。 再次恭喜 @AnthropicAI 团队这次发布!
Real-world results are in for Claude Haiku 5.5 (High) by @AnthropicAI. Debuting at #30 with 1587 pts in Code Arena: WebDev, this release sits just outside the Pareto frontier while still offering strong cost efficiency. It matches GPT‑6 Luna’s price at $0.10/$0.50 per 1M input/output tokens while scoring six pts higher. Compared with other Claude models, Haiku 5.5 offers: - 90% lower cost than Haiku 4.5 at +257 pts - 95% lower cost than Sonnet 5.5 (High) at -128 pts - 98% lower cost than Opus 5 (High) at -70 pts - 99% lower cost than Fable 5.1 (Max) at -157 pts Congrats to the team at @AnthropicAI on this release!
查看被引用的帖子Claude Haiku 5.5 (High) 由 @AnthropicAI 打造,在 Agent Arena 中综合排名第 27。 详情请看:arena.ai/leaderboard/agent